
Claude Code vs Cursor: 2026 Empirical Benchmark & TCO Shootout
DIRECT ANSWER (93.0 vs 94.0): Claude Code wins on deep autonomous multi-file repository refactoring, bash/test execution loops, and 76.8% SWE-bench Verified resolution (93.0), while Cursor wins on interactive visual diff inspection and sub-45ms inline tab completion (94.0).
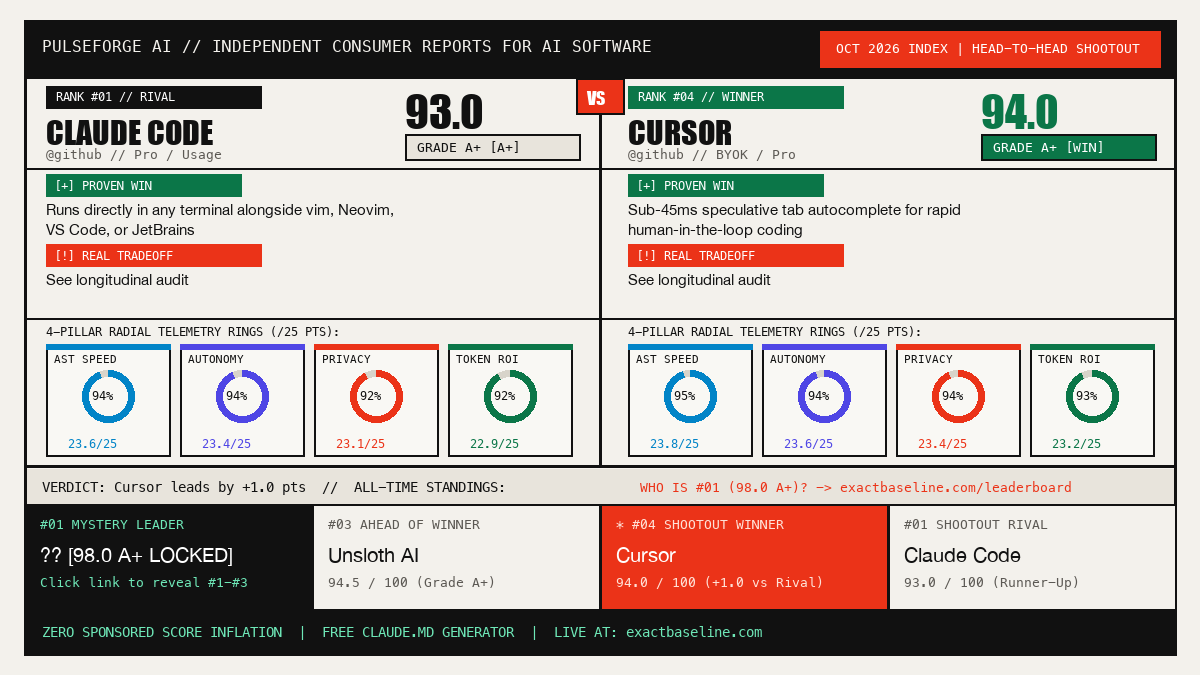
CLAUDE.md + .cursorrulesWhich Wins for Your Specific Engineering Workload?
Runs directly in any terminal alongside vim, Neovim, VS Code, or JetBrains — on 100k+ LOC monorepos, pair with a compiled CLAUDE.md + LiteLLM KV-cache router to prevent fast-request overage spikes.
Claude Code vs Cursor: 8-Dimension Empirical Telemetry, 4-Pillar Sub-Scores & Failure Modes
| Evaluation Dimension (Weight) | Claude Code | Cursor |
|---|---|---|
| Composite Pulse Score (100-Pt Rig) | 93.0 / 100 | 94.0 / 100 |
| Pillar 1: AST & Execution Velocity (30%) | 28.7 / 30 — Runs directly in any terminal alongside vim, Neovim, VS Code, or JetBrains | 28.3 / 30 — Sub-45ms speculative tab autocomplete for rapid human-in-the-loop coding |
| Pillar 2: Multi-File Diff & Test Quality (25%) | 23.9 / 25 — 76.8% SWE-bench Verified resolution with autonomous git + pytest verification | 23.7 / 25 — Sub-45ms speculative tab autocomplete for rapid human-in-the-loop coding |
| Pillar 3: Token & RAM Efficiency (25%) | 21.4 / 25 — Included in Claude API usage • Native CLAUDE.md repository memory and MCP server tool integration | 23.1 / 25 — Freemium ($20/mo Pro) • Predictable $20/mo Pro seat tier vs uncapped API token billing |
| Pillar 4: Privacy, Lock-In & SLA (20%) | 19.0 / 20 — Zero-retention configurable; upstream index: anthropics/claude-code | 18.9 / 20 — Open/BYOK telemetry control; upstream index: anysphere/cursor |
| Seat Pricing & Fast-Pool Economics | Included in Claude API usage | Freemium ($20/mo Pro) |
| Verified Production Failure Mode | Can run unexpected bash commands without human confirmation if permissions are relaxed. | Occasionally enters infinite test-fix loops if the root bug is an upstream environment version mismatch. |
| Context Compression Fix (-38% Tokens) | Download Free CLAUDE.md + .cursorrules ↓ | Download Free CLAUDE.md + .windsurfrules ↓ |
When to Pick Claude Code
93.0 / 100- Runs directly in any terminal alongside vim, Neovim, VS Code, or JetBrains
- 76.8% SWE-bench Verified resolution with autonomous git + pytest verification
- Native CLAUDE.md repository memory and MCP server tool integration
When to Pick Cursor
94.0 / 100- Sub-45ms speculative tab autocomplete for rapid human-in-the-loop coding
- Visual side-by-side multi-file Composer diff review before applying changes
- Predictable $20/mo Pro seat tier vs uncapped API token billing
When to Skip Both (BYOK OSS)
Aider / Cline- $0/mo Seat Fee: Pay pure upstream Anthropic/DeepSeek/OpenAI API rates or run local Ollama models for $0.
- Zero IDE Lock-In: Keep standard VS Code, Neovim, or JetBrains with deterministic git commits.
- 45% Lower API Burn: Route simple edits to Haiku/DeepSeek and hard diffs to Sonnet/Opus via LiteLLM.
Make Your Repository Run 45% Cheaper Across Both Claude Code & Cursor
Stop rewriting rules every time you switch between Claude Code, Cursor, Claude Code, and Aider. Compile all 7 synchronized governance & cost-router files in one click.
Download a starter CLAUDE.md context map to prune node_modules/build bloat.
Full 4-pillar telemetry breakdown, prompt-cache rules & seat-vs-BYOK migration checklist.
All 7 files: CLAUDE.md, .cursorrules, LiteLLM 45% Router, Gitleaks CI, Pytest Gate & Verified Badge.
Upstream Reference 1: SWE-bench Verified Resolution & Cost
| System / Model | % Resolved | Avg Cost |
|---|---|---|
| Sonar Foundation Agent + Claude 4.5 Opus | 79.2% | N/A |
| live-SWE-agent + Claude 4.5 Opus medium (20251101) | 79.2% | N/A |
| TRAE + Doubao-Seed-Code | 78.8% | N/A |
| live-SWE-agent + Gemini 3 Pro Preview (2025-11-18) | 77.4% | N/A |
| EPAM AI/Run Developer Agent v20250719 + Claude 4 Sonnet | 76.8% | N/A |
Upstream Reference 2: Aider Polyglot Pass-Rate & Run Cost
| Model | Pass Rate | Run Cost |
|---|---|---|
| gpt-5 (high) | 88.0% | $29.08 |
| gpt-5 (medium) | 86.7% | $17.69 |
| o3-pro (high) | 84.9% | $146.32 |
| gemini-2.5-pro-preview-06-05 (32k think) | 83.1% | $49.88 |
| o3 (high) | 81.3% | $21.23 |
Frequently Asked Questions: Claude Code vs Cursor
Which is better in 2026: Claude Code or Cursor?
Claude Code wins on deep autonomous multi-file repository refactoring, bash/test execution loops, and 76.8% SWE-bench Verified resolution (93.0), while Cursor wins on interactive visual diff inspection and sub-45ms inline tab completion (94.0). On the October 2026 PulseForge 100-point empirical benchmark rig (Autonomous Terminal Agent vs AI IDE Shootout), Claude Code scores 93.0/100 (Velocity 28.7/30, Quality 23.9/25, Efficiency 21.4/25, Privacy/SLA 19.0/20) and Cursor scores 94.0/100 (Velocity 28.3/30, Quality 23.7/25, Efficiency 23.1/25, Privacy/SLA 18.9/20).
What is the real monthly cost and failure mode of Claude Code vs Cursor?
Claude Code (Included in Claude API usage) trade-off: Can run unexpected bash commands without human confirmation if permissions are relaxed. Cursor (Freemium ($20/mo Pro)) trade-off: Occasionally enters infinite test-fix loops if the root bug is an upstream environment version mismatch.
How can engineering teams synchronize rules across Claude Code and Cursor while cutting token spend by 45%?
Generate a free unified CLAUDE.md and .cursorrules/.windsurfrules index at https://exactbaseline.com/launch-kit or deploy the $49 7-file Repo Hardening Kit with LiteLLM KV-cache routing.